My research focuses on LLM evaluation, LLM-as-a-Judge, rubric-based evaluation, and machine learning.
I am particularly interested in evaluating judges on long-horizon agent trajectories and building reliable
reward models for complex tasks. I plan to pursue a Ph.D. and continue research in academia.
I am deeply grateful to my mentor,
Shudong Liu, who introduced me to
research and has supported me immensely along the way. I am also sincerely grateful
to my advisor, Prof. Derek F. Wong,
for his guidance and support in my research. I will keep working hard
to live up to the guidance and help I have received from my labmates, professors,
and friends in the lab.
I am looking to pursue a Ph.D. and continue my research in academia.
Please feel free to reach out via email.
我由衷感谢我的 mentor 刘树东,
是他领我进入学术之门,并一路给予我莫大的帮助。我也衷心感谢导师
Derek F. Wong 教授在科研中给予我的指导与支持。
我会继续努力,不辜负实验室师兄、教授与同伴对我的指导和帮助。
我希望继续攻读博士学位,在学术界深耕。欢迎通过邮件与我联系。
§ 02Research Overview研究方向THEMATIC PILLARS研究主题
I.
LLM Reliability & Safety Evaluation大模型可靠性与安全评测
Building rigorous benchmarks to evaluate LLM judges, scoring rubrics, and the reliability of model-generated assessments.
构建严谨的评测基准,衡量 LLM 判官、评分标准及模型生成评价的可靠性。
II.
Trustworthy Agents & Deep Research可信智能体与深度研究
Studying error detection, evidence tracing, and recovery in long-horizon agents and deep research, towards reliable agent training and multi-agent collaboration.
关注长程智能体与深度研究系统的错误检测、证据回溯和自主纠错,探索可靠的智能体训练与多智能体协作。
III.
Reward Modeling & Reward Hacking奖励模型与奖励投机
Evaluating reward-model reliability and robustness, and investigating how agents exploit reward signals and how to detect and mitigate such behavior.
评测奖励模型的判断能力与鲁棒性,研究智能体如何利用奖励机制的漏洞,以及如何识别和缓解这些行为。
I also maintain an active interest in agent hardness, agent skills, and AI watermarking, and closely follow the latest research developments in these emerging areas.
同时对 agent hardness、智能体技能(agent skills)与 AI 水印等前沿方向保持积极兴趣,并持续跟踪相关领域的最新研究进展。
§ 03News动态RECENT近况
2026-10Submitted LongJudgeBench and CIFE to the October 2026 ACL Rolling Review (ARR).LongJudgeBench 与 CIFE 已投稿至 2026 年 10 月 ACL Rolling Review(ARR)。
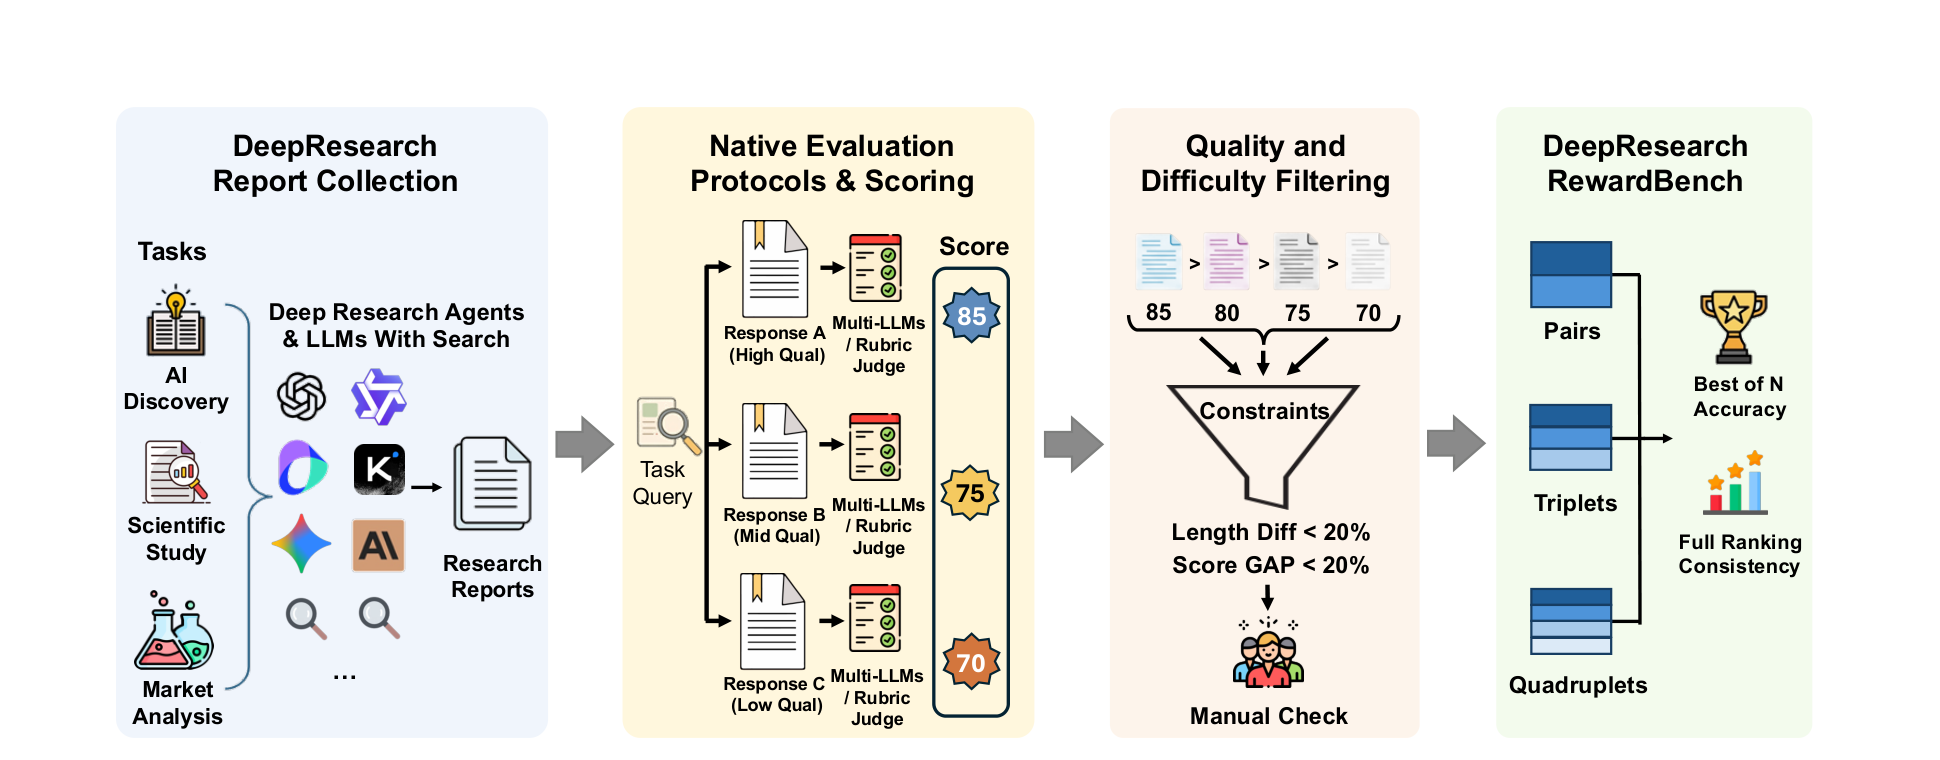
2026-08DeepResearch RewardBench: Evaluating Reward Models for Deep Research Reports was accepted to Findings of EMNLP 2026.DeepResearch RewardBench: Evaluating Reward Models for Deep Research Reports 被 EMNLP 2026 Findings 接收。
2026-05Submitted DeepResearch RewardBench: Evaluating Reward Models for Deep Research Reports to EMNLP.向 EMNLP 投稿 DeepResearch RewardBench —— 面向深度研究报告的奖励模型评测基准。
2025-08Started the M.S. program in Data Science (Artificial Intelligence) at the University of Macau and joined the NLP2CT Lab.开始在澳门大学攻读数据科学(人工智能应用方向)硕士学位,并加入 NLP2CT 实验室。
2025-07Graduated from Guangdong University of Foreign Studies with an Honours Degree and the Outstanding Graduate Award.毕业于广东外语外贸大学,获荣誉学位及优秀毕业生称号。
Research Assistant — NLP2CT Lab, University of Macau研究助理 —— NLP2CT 实验室,澳门大学2025 – Present
DeepResearch RewardBench (co-first author) — built the first reward-model benchmark for long-form deep-research reports: an end-to-end pipeline over 19 agent/LLM families yielding preference datasets of 331 tasks / 866 reports, evaluation of 17 models (7B–235B), and a few-shot judge-error classifier reaching ~87% agreement with humans. Accepted to Findings of EMNLP 2026.
CIFE (co-first author) — developed a glossary-grounded, item-level metric for cultural fidelity in literary machine translation. It grades each cultural item with an evidence-checked LLM judgment and was evaluated on English translations of Journey to the West and a Telugu Ramayana; submitted to October 2026 ACL Rolling Review.
LongJudgeBench (first author) — built a benchmark of 590 natural agent trajectories and 262 constructed error cases to measure LLM judges' error detection, localization, and evidence attribution; submitted to October 2026 ACL Rolling Review.
Benchmarks three LLM-judge capabilities on agent trajectories: error detection, localization, and attribution of supporting execution evidence. It contains 590 natural trajectories and 262 constructed error cases across five error families; evaluation of 10 judges revealed a substantial evidence-attribution gap.
CIFE (Glossary-Grounded, Item-Level Evaluation of Cultural Fidelity in Literary Machine Translation) evaluates cultural items individually. An LLM assigns strategy-constrained severity scores and quotes translation evidence that is automatically checked; evaluated on Journey to the West and a Telugu Ramayana.
LLM-as-a-Judge · Cultural Fidelity · Machine Translation Evaluation
DeepResearch RewardBenchaccepted已接收
A benchmark for evaluating how well reward models score long-form deep-research reports, probing their reliability as judges. Accepted to Findings of EMNLP 2026.
ACL Rolling Review · October 2026ACL Rolling Review · 2026 年 10 月2026
LongJudgeBench: Benchmarking LLM Judges on Agent Trajectory Error Localization and Evidence AttributionYuting Zhong (first author).钟玉婷(第一作者)。Submitted to ACL Rolling Review (ARR), October 2026.已投稿至 ACL Rolling Review (ARR),2026 年 10 月。
Findings of EMNLP 2026EMNLP 2026 Findings2026
DeepResearch RewardBench: Evaluating Reward Models for Deep Research ReportsShudong Liu*, Yuting Zhong*, Guanhua Chen, Xinyi Yang, Junnan Liu, Lidia S. Chao, Jiaheng Liu, and Derek F. Wong.To appear in Findings of EMNLP 2026.将发表于 EMNLP 2026 Findings。
ACL Rolling Review · October 2026ACL Rolling Review · 2026 年 10 月2026
CIFE: Glossary-Grounded, Item-Level Evaluation of Cultural Fidelity in Literary Machine TranslationBhaskar Ganesh Devalla*, Yuting Zhong*, Dejing Zhou, Junchao Wu, Shudong Liu, Lidia S. Chao, and Derek F. Wong.Submitted to ACL Rolling Review (ARR), October 2026.已投稿至 ACL Rolling Review (ARR),2026 年 10 月。
§ 08Honors & Awards荣誉奖项AWARDS荣誉
Provincial Second Prize, Chinese Mathematics Competition for College Students.全国大学生数学竞赛 省级二等奖。
Outstanding Graduate Award, Guangdong University of Foreign Studies.广东外语外贸大学 优秀毕业生。
University Comprehensive Scholarship (multiple times).大学综合奖学金(多次)。
“Merit Student” & “Outstanding Class Cadre” honors (multiple times).校级“三好学生”、“优秀班干部”等荣誉(多次)。
Graduate (UM):研究生(澳大):Applied Natural Language Processing, Deep Learning, Practical Machine Learning, Principles of Artificial Intelligence应用自然语言处理、深度学习、实用机器学习、人工智能原理
Undergraduate:本科:Algorithm Design, C++ Programming, Natural Language Processing, Big Data Processing算法设计、C++ 程序设计、自然语言处理、大数据处理技术